The release of Seedance 2.5 has pushed AI video creation further toward reference-driven and multimodal production. With support for continuous video generation of up to 30 seconds in standard mode and up to 50 multimodal inputs, creators can provide more information about characters, scenes, movement, style, and overall creative direction before generation.
Whether the goal is a multi-character advertising scene, a corporate presentation, or an ecommerce product video, these additional references can make it easier to communicate the intended visual direction to the model.
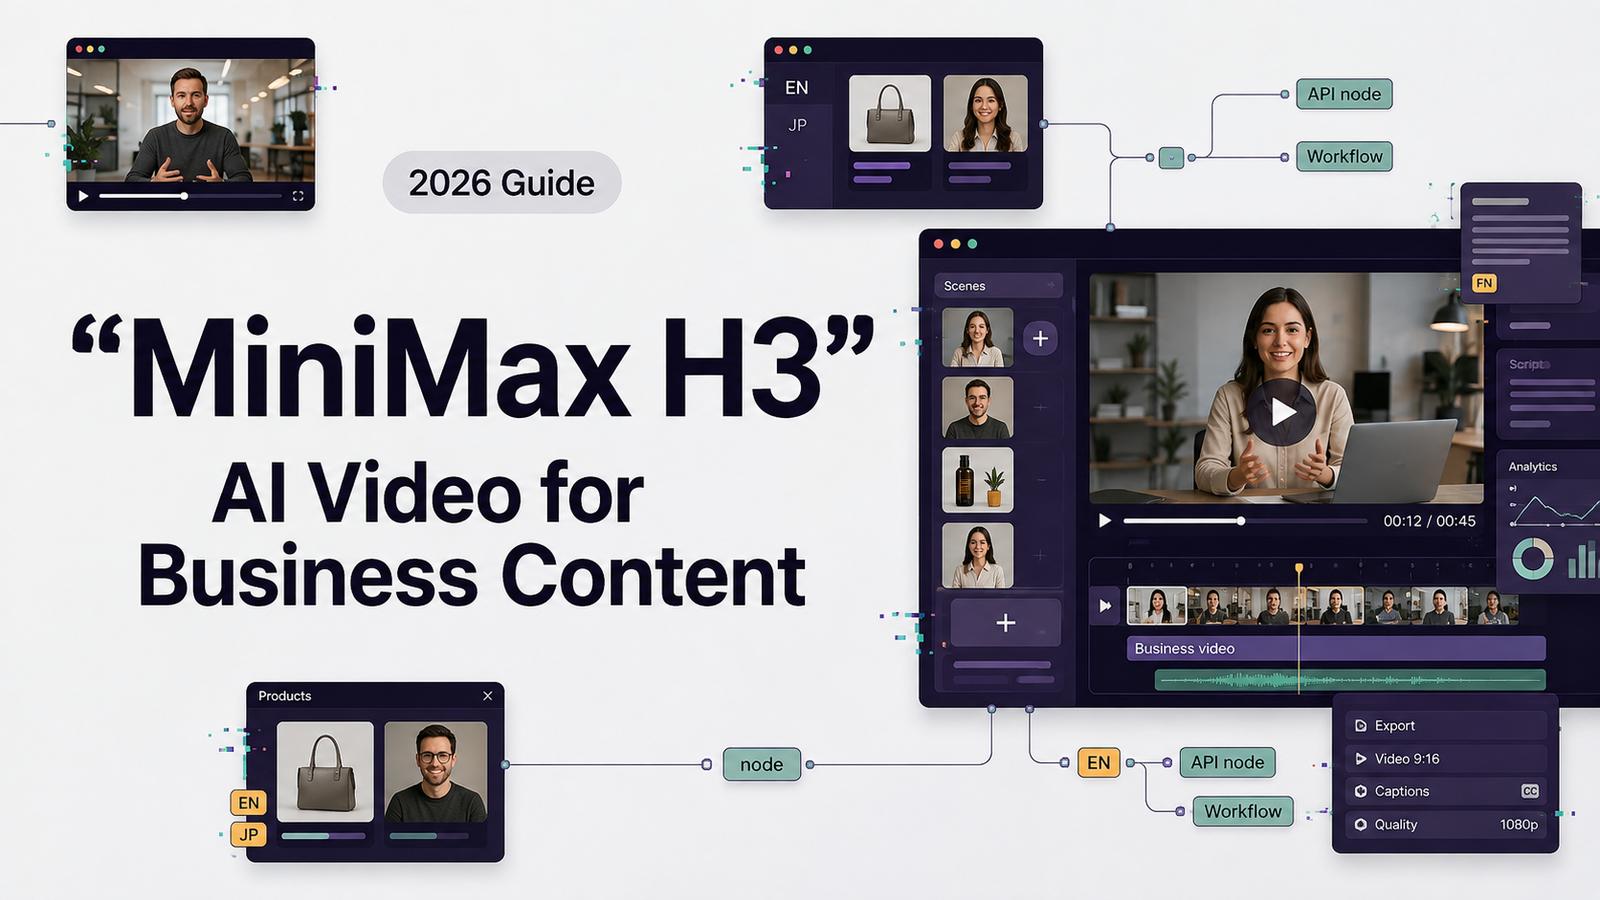
But generating the original presenter footage is only one part of a global content workflow. Once a high-quality AI presenter clip needs to be adapted for different languages and markets, another challenge appears: how can teams localize the video while keeping the presenter visually natural and the spoken content synchronized?
For brands expanding across regions, this makes the connection between AI video generation, AI avatars, lip sync, and video localization increasingly important. This is where Wizstar can fit into the workflow, helping creators move from generated presenter footage toward localized digital human content.
Bridging Generation and Localization: The Wizstar Workflow
Seedance 2.5 can provide the initial creative foundation, while Wizstar can be used as the next step for turning that footage into localized digital presenter content.
The workflow can be understood as:
Seedance 2.5 Master Video → Wizstar AI Avatar / Localization Workflow → Multilingual Content
This separation is useful because the two stages solve different problems. Seedance 2.5 focuses on generating the scene and visual concept, while an avatar and localization workflow focuses on adapting the presenter and spoken content for different audiences.
Wizstar brings these steps into a broader AI video creation workflow, making it possible to start with existing visual material rather than rebuilding every localized video from scratch.
1. High-Precision Lip Sync for More Natural Presenters
The Business Problem: When a presenter speaks in another language, the audio changes while the original facial movement remains tied to the source performance. Poor synchronization can make the localized video feel unnatural.
The Wizstar Approach: Wizstar's AI video workflow can be used to synchronize spoken content with facial movement, helping create more natural-looking localized presenter videos.
Rather than treating translation as a separate text-only task, the workflow connects language adaptation with the visual presentation of the speaker.
Real-World Value: For ecommerce brands, marketers, and training teams, the same presenter concept can be adapted for different language markets without requiring an entirely new recording for every version.
2. Support More Natural Presenter Angles and Movement
Seedance 2.5 can be used to create more varied visual compositions and reference-driven scenes. When these clips are subsequently localized, maintaining natural facial movement across different angles becomes important.
Wizstar's avatar workflow is designed to work with video-based presenter content rather than limiting the entire creation process to a single static talking-head setup.
This makes the combination useful for content that includes product demonstrations, social media presenters, educational videos, or promotional sequences with more dynamic visual compositions.
Real-World Value: Teams can create the visual concept first and then use the resulting footage as the foundation for multilingual presenter content, reducing the need to recreate the entire visual concept for every market.
3. Photo-Based AI Avatars for Faster Content Production
Another useful part of an AI avatar workflow is the ability to create presenter content from existing visual assets.
Wizstar's AI Avatar workflow supports photo-based avatar creation, allowing teams to start from an existing image rather than requiring a traditional studio recording for every new presenter concept.
This can be particularly useful when brands already have executive portraits, campaign images, product presenters, or other approved visual assets.
For global campaigns, this provides another route for reusing existing visual resources across different content variations.
Comparison: Traditional Avatar Workflows vs. Wizstar AI Pipeline
The difference is easier to understand when the workflow is viewed as a complete production process rather than as a single avatar feature.
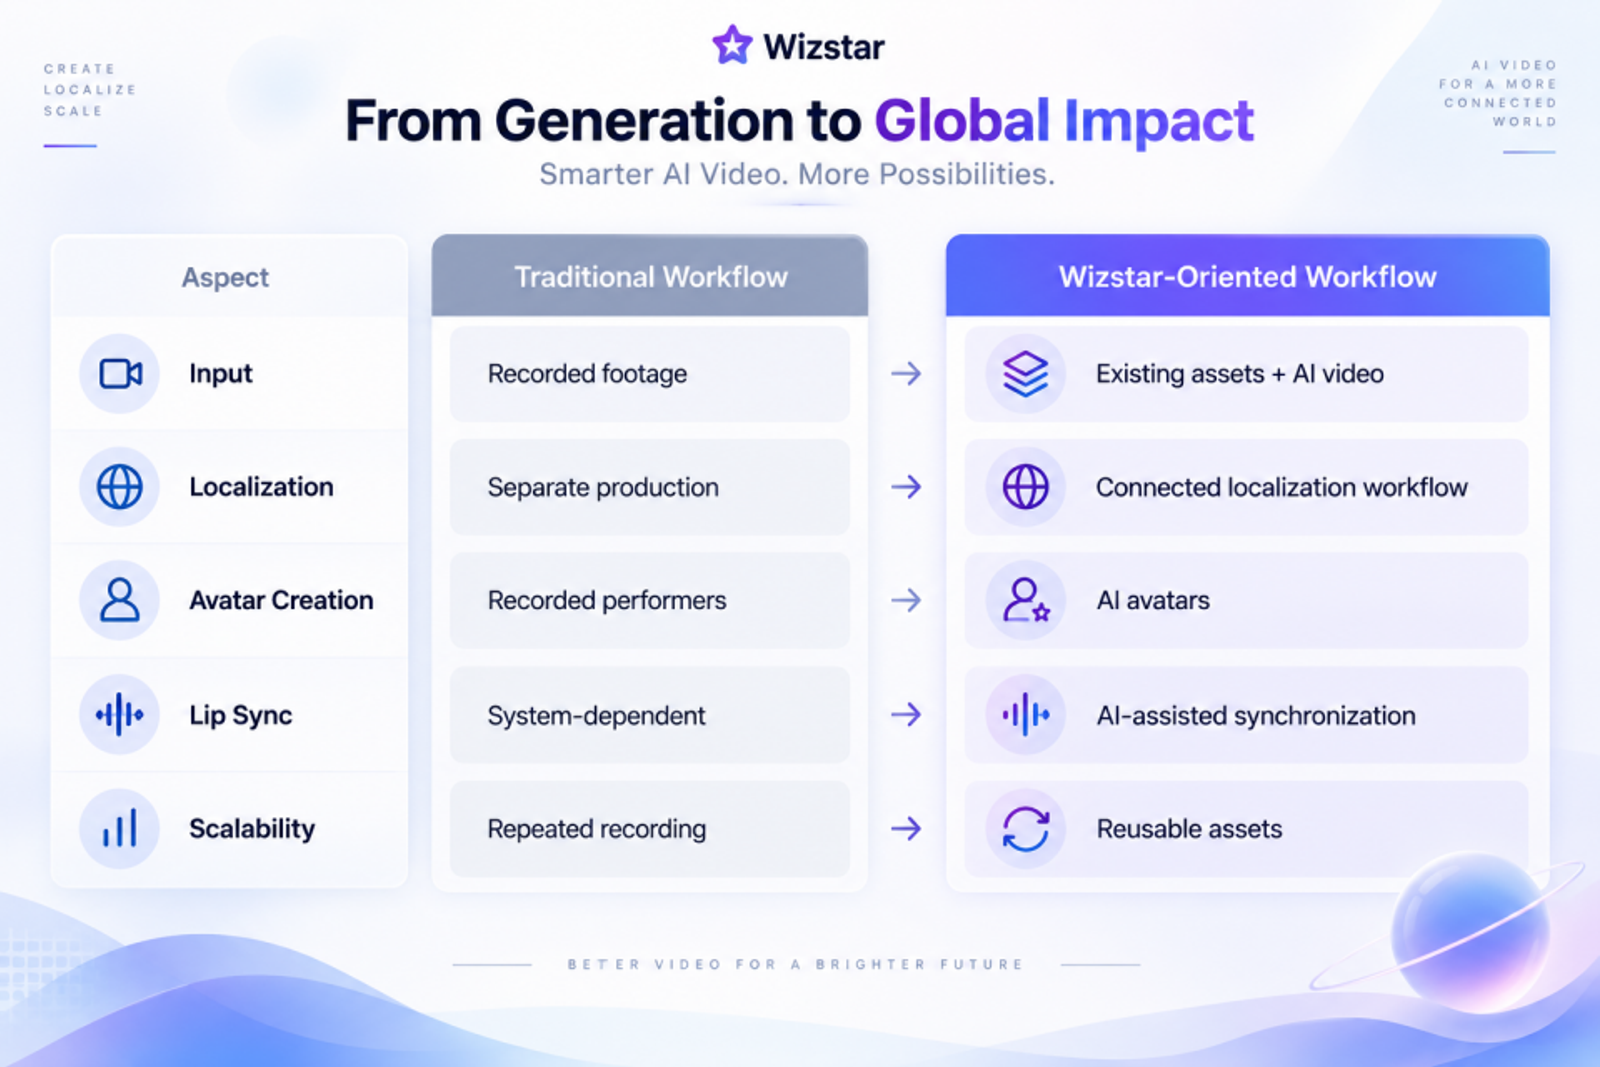
The main difference is therefore not simply which tool has more features. It is how easily the generated visual assets can move into the next stage of content production.
Real-World Workflow: Scaling Seedance 2.5 Digital Presenters for Global Content
Combining Seedance 2.5 with Wizstar can be understood as a two-stage production workflow: first create the visual concept, then adapt it for different audiences.
Step 1: Generate the Master Presenter Footage
Use Seedance 2.5's multimodal capabilities and reference-driven generation to establish the presenter, scene, movement, and overall visual direction.
Standard generation supports videos of up to 30 seconds, while the model can use up to 50 multimodal inputs as part of the creative workflow.
Step 2: Bring the Generated Footage Into Wizstar
Use the generated presenter footage as the starting material for AI avatar and localization workflows.
This allows teams to separate visual creation from language adaptation instead of recreating the entire video for every target market.
Step 3: Localize the Presenter Content
Adapt the spoken content for the target language and use AI-assisted facial animation and lip synchronization to create localized presenter versions.
The exact result will depend on the source footage, language, audio, reference materials, and generation workflow.
Step 4: Create Market-Specific Content Variations
The localized presenter footage can then be adapted for different marketing, ecommerce, social media, or training scenarios.
This creates a more reusable production path:
Seedance 2.5 Visual Creation → Wizstar Localization → Market-Specific Video Content
Start Scaling Your Digital Presenters Globally
Generating an AI presenter is only the beginning. For global content production, the larger challenge is turning that initial visual asset into versions that can work across different languages, audiences, and channels.
Seedance 2.5 provides a stronger foundation for reference-driven video creation, including 30-second continuous generation, multimodal inputs, R2V references, localized editing, and 4K output.
Wizstar can then extend that workflow into AI avatar and localization use cases, allowing teams to work from generated footage and existing visual assets instead of rebuilding every localized video from the beginning.
The goal is not to replace creative review or human direction. It is to make the assets created at one stage more reusable in the stages that follow.
For brands producing product videos, advertising creatives, social content, corporate presentations, or multilingual training materials, this can provide a more connected path from AI video generation to global digital presenter content.
Conclusion: From AI Video Generation to a Reusable Content Workflow
The value of Seedance 2.5 is not limited to generating visually impressive clips. Its multimodal references and reference-driven workflows give creators more ways to communicate the intended result before generation.
For global marketing teams, however, the creation stage is only part of the process. Once the master video is ready, localization, avatar adaptation, and lip synchronization become equally important to turning that asset into usable regional content.
This is where the combination of Seedance 2.5 and Wizstar becomes practical. Seedance 2.5 can serve as the visual generation layer, while Wizstar can connect the resulting footage with AI avatar and localization workflows.
Instead of treating AI video generation and avatar localization as two isolated tasks, teams can build a more reusable pipeline:
Create → Localize → Adapt → Scale
That shift can make AI-generated presenter content more practical for brands that need to create and adapt video content across markets.