Seedance 2.5 is everywhere right now. As someone who has been creating AI video content for a while, I wanted to try it as soon as possible. The model itself was impressive, but after actually using it for different video projects, I felt there was still one thing I needed to figure out: how to write better Seedance 2.5 prompts that produce more controllable results.
So I went back to ByteDance's recent official Seedance 2.5 prompt guide, then tested those ideas several more times in Wizstar using Seedance 2.5. I tried product videos, character-driven scenes, and different visual setups, and after a lot of tweaking, I realized that I didn't need to memorize dozens of complicated prompt formulas.
I kept coming back to five things.
These aren't meant to be a universal formula for every AI video generator. They're simply the five prompt techniques that have made the biggest difference in my own Seedance 2.5 workflow. If you're also experimenting with Seedance 2.5 prompts, these are the areas I'd focus on first.
Get the Order Right
This is probably the biggest thing I changed after testing Seedance 2.5 more seriously.
When I first started writing AI video prompts, I often assumed that more detail meant better results. So I'd keep adding words like:
cinematicrealisticpremiumdramatic lighting4Kcommercial style
These words can certainly help define a visual direction. But I've found that how the information is organized matters more than simply adding more descriptive words.
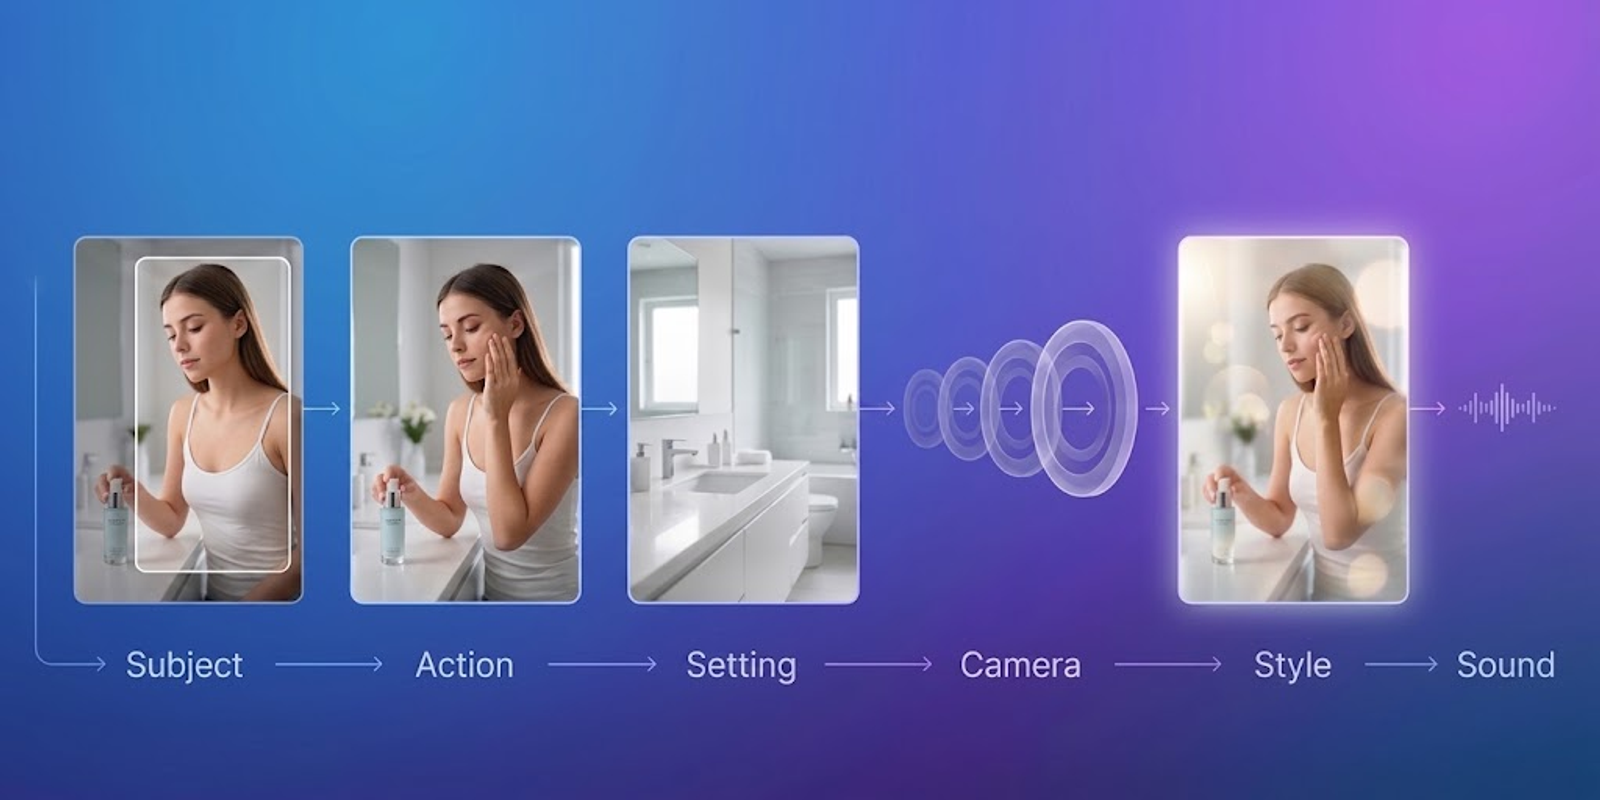
For Seedance 2.5, I now usually start with a simple structure:
Subject → Action/Event → Setting → Camera → Visual Style → Sound
This isn't a rigid prompt formula that every video has to follow. It's simply a useful way to organize the information.
For example, if I'm creating a skincare product video, I wouldn't start with:
cinematic, realistic, premium skincare commercial, beautiful lighting
I'd first describe what is actually happening:
A young woman in a bright modern bathroom picks up a skincare bottle from the counter and applies the product to her cheek.
Then I can add:
Soft natural daylight, shallow depth of field, slow camera push-in.
The first part tells the AI video model what is happening. The second part tells it how the scene should look and feel.
That distinction matters.
The same principle also appears in ByteDance's official Seedance 2.0 materials, where text, images, audio, and video can all provide different types of information, including characters, environments, actions, camera movement, visual effects, and sound.
So when I write a prompt now, my first question isn't:
"What other cinematic keywords can I add?"
It's:
"What exactly is happening in this shot?"
Once that is clear, the visual style becomes much easier to control.
I've found this especially useful when creating e-commerce videos in Wizstar with Seedance 2.5. I usually define what the product and character are doing first, then refine the camera and visual style afterward.
In other words, the order of your AI video prompt can matter more than the number of keywords you put into it.
Give Every Reference a Job
This is something I noticed very quickly when testing Seedance 2.5 with Wizstar.
Wizstar's video generator supports multimodal references, including images, videos, audio, and prompts. It also supports reference-to-video, first-frame-to-video, start-and-end-frame generation, and text-to-video workflows. With Seedance 2.5, videos can be generated from 4 to 30 seconds.
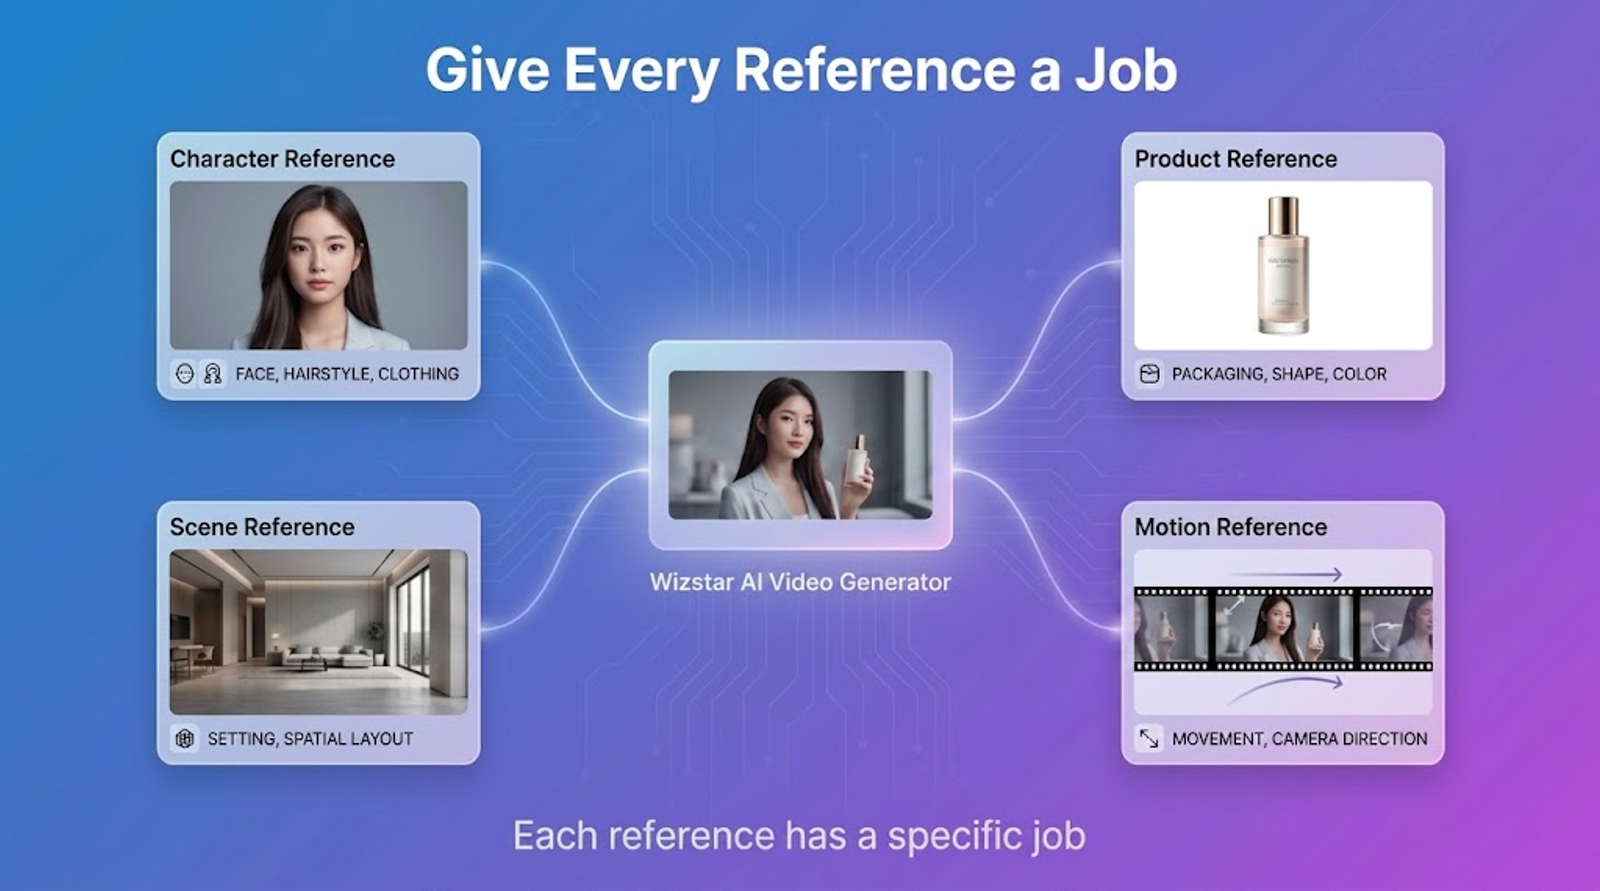
So for a product video, I might have:
- A character reference image
- A product image
- A scene reference
- A motion reference video
At first, it's tempting to upload everything and simply start generating.
But after testing different combinations, I found that this isn't always the most controllable approach.
Once you provide several references, the model still needs to figure out what information it should take from each one.
Should the character image define the person only?
Should its background also be used?
Should the product image determine the entire scene?
Should the motion reference control the character's movement, the camera movement, or both?
That's why I now give each reference a clear role.
For example:
@Image1 defines the character's face, hairstyle, and clothing.@Image2 defines the product's packaging, shape, and color. Do not use its background.@Image3 defines the environment and spatial layout.@Video1 provides the movement and camera direction.
This small change makes a big difference.
I'm no longer simply telling the model:
"Use these references."
I'm telling it:
"Use this reference for this specific information, and don't use it for something else."
For example, if a product image has a background I don't want in the final video, I'll explicitly tell the model to focus on the product and not reproduce the original background.
The same applies to character references. If I only need the face, hairstyle, and clothing, I don't necessarily want the original location to carry over.
This is where multimodal prompting becomes much more useful.
The character reference defines the character. The product image defines the product. The scene reference defines the environment. The motion reference defines movement.
And more references don't automatically mean better results.
Seedance 2.5's official materials describe support for up to 50 multimodal reference inputs, but that doesn't mean I try to use as many references as possible.
I usually prefer fewer, more purposeful references over a pile of repetitive ones.
So the rule I keep coming back to is simple:
After uploading references, tell the model what each one is responsible for—and what it should not be used for.
Break Long Videos Into Stages—and Connect Them
This is one of the most useful ideas I took away from the official Seedance 2.5 prompt guidance and my own longer video tests.
Seedance 2.5 supports video generation of up to 30 seconds, and the official prompt guidance includes examples of structuring longer videos into different stages.
The important part isn't simply dividing a 30-second video into three paragraphs.
It's giving the video a clear progression.
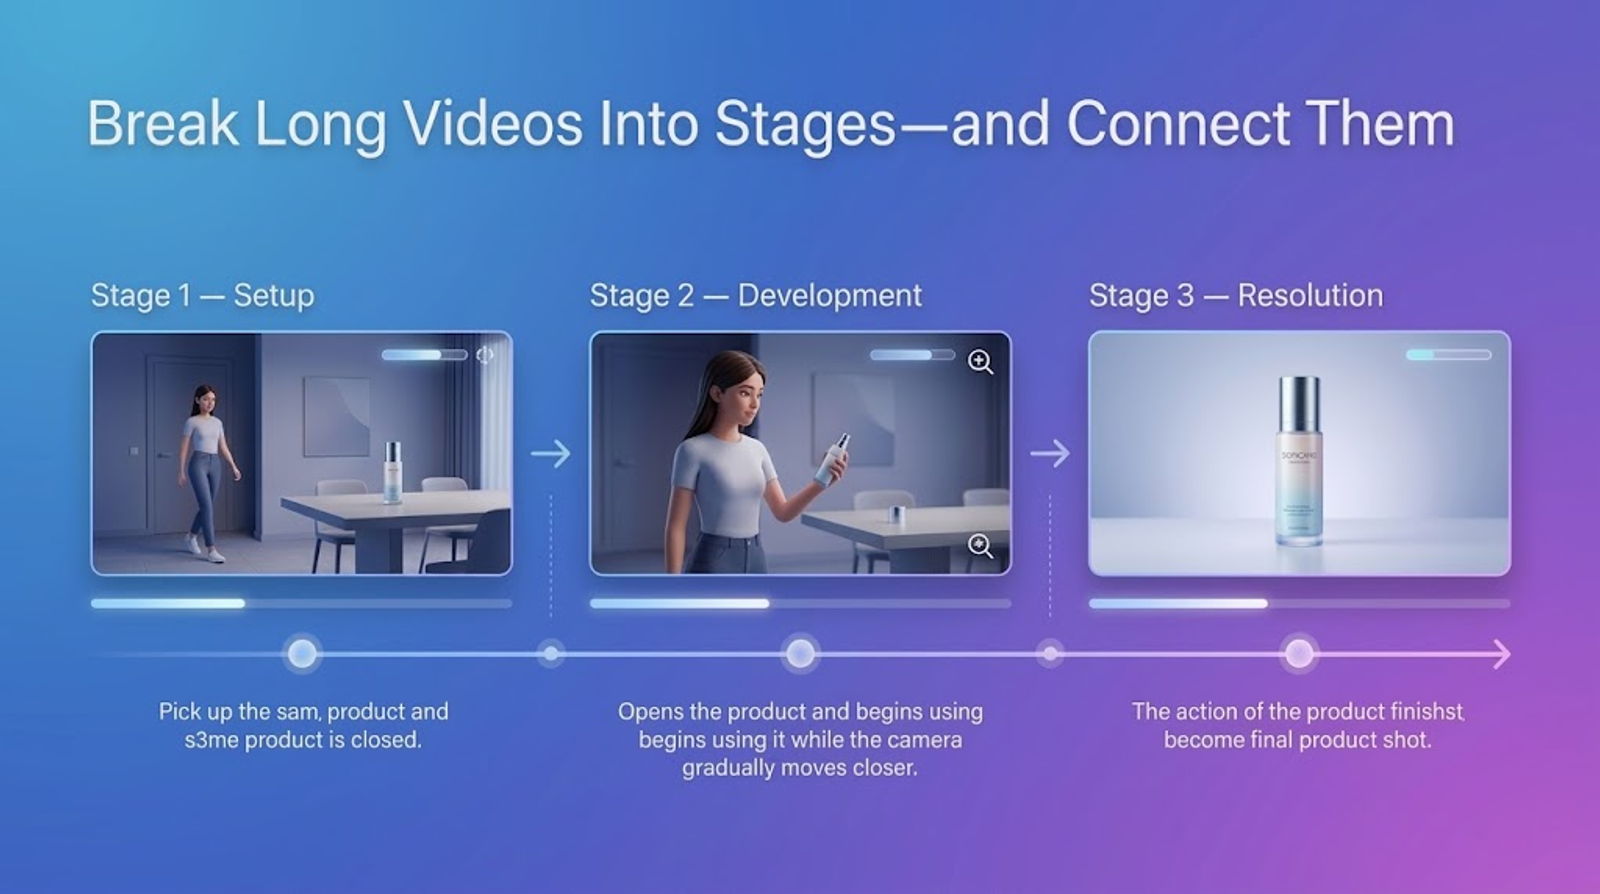
For example, a product commercial might be structured like this:
Stage 1: Setup
The character enters the room, walks to the table, and picks up the product.
Stage 2: Development
The character opens the product and begins using it while the camera gradually moves closer.
Stage 3: Resolution
The action finishes, the product becomes the visual focus, and the camera moves into the final product shot.
The key is that each stage should have one primary state change.
I wouldn't try to pack all of these into one stage:
Walk in → pick up the product → open it → use it → turn around → rotate the camera → show the product.
That's too many major changes at once.
Instead, I want each stage to answer one simple question:
What changes during this part of the video?
But there's another detail that I now pay even more attention to:
What is still visible at the end of each stage?
This is where continuity becomes really important.
Imagine Stage 1 ends with the character standing beside the table, holding the product in her right hand, with the cap still closed.
When Stage 2 begins, I don't want to simply write:
Stage 2: The woman opens the product and starts using it.
I'd rather write something like:
Continue from the previous stage. The woman is still standing beside the table, holding the same product in her right hand. The cap remains closed.
Now the model has a much clearer starting point.
The character is still there.
The product is still there.
Her position is still defined.
The product's state is still defined.
This is why I think there are really two things to control when writing longer AI video prompts:
Timeline: What happens next?
Continuity: What from the previous stage needs to remain?
When I use Seedance 2.5 in Wizstar for longer product videos, I pay particular attention to this handoff between stages. If the character has already picked up the product in Stage 1, I explicitly carry that state into Stage 2 before describing the next action.
The goal isn't to make the prompt look more sophisticated. It's to avoid making the model reconstruct the character, product, and scene from scratch every time a new stage begins.
So the real lesson from the staged prompt approach isn't simply:
"Split your prompt into three sections."
It's:
Use stages to control state changes, and use continuity descriptions to connect those stages.
Show the Emotion Through Action
This is another technique I use a lot when creating character-driven AI videos.
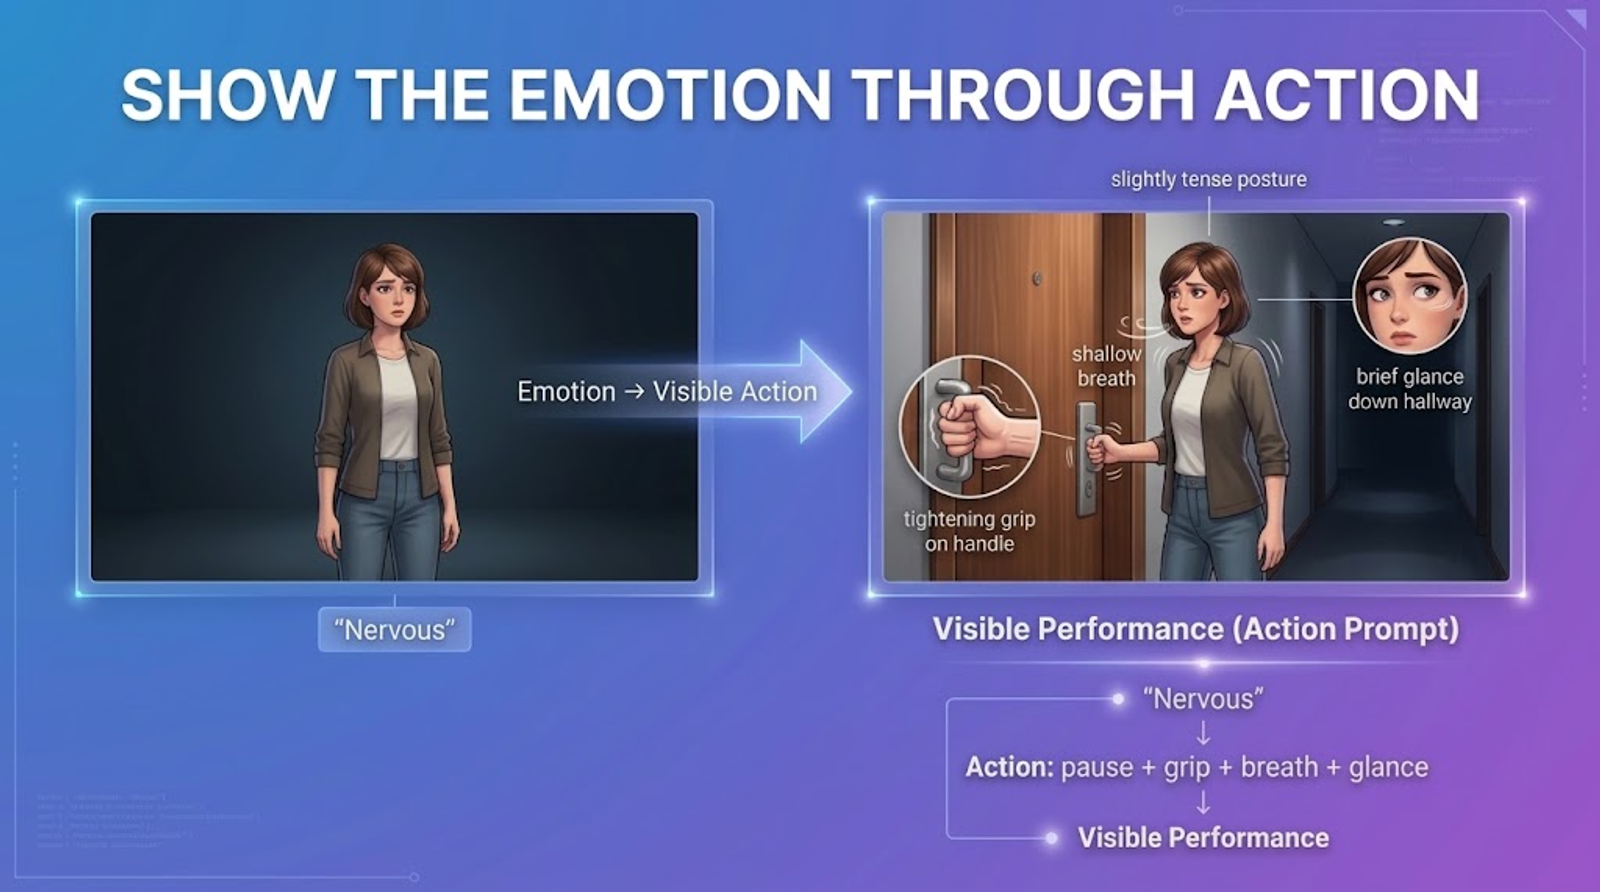
Let's say I want a character to look nervous.
The obvious prompt would be:
The character looks nervous.
That's understandable, but it doesn't tell the model exactly how that nervousness should appear on screen.
Should the character frown?
Avoid eye contact?
Grip something tightly?
Take a breath?
Step backward?
So instead, I often translate the emotion into visible actions:
She pauses before opening the door, tightens her grip on the handle, takes a shallow breath, and briefly looks toward the hallway.
Notice that the word "nervous" isn't even necessary anymore.
The emotion is communicated through behavior.
The same approach works for other emotions.
Instead of simply writing happy, you can describe a natural smile, relaxed shoulders, or the character leaning toward someone.
Instead of surprised, describe widened eyes, raised eyebrows, or a small step backward.
Instead of hesitant, describe a pause, a glance away, or a hand reaching forward and pulling back.
The reason I like this approach is simple:
Emotion is abstract. Action is visible.
An AI video model ultimately has to turn your prompt into things that appear on screen. Describing what the character physically does gives it something much more concrete to work with.
I've found this especially useful for marketing videos and digital human content. For example, if I want a digital presenter to feel enthusiastic while introducing a product, simply writing "enthusiastic" is still fairly broad. Describing when the presenter smiles, looks toward the product, or raises the product for the camera gives the model a much clearer performance direction.
So whenever I need to control emotion, I now ask myself:
"What would this emotion actually look like on camera?"
Then I describe that.
Don't just tell the model what the character feels. Tell it what the character does.
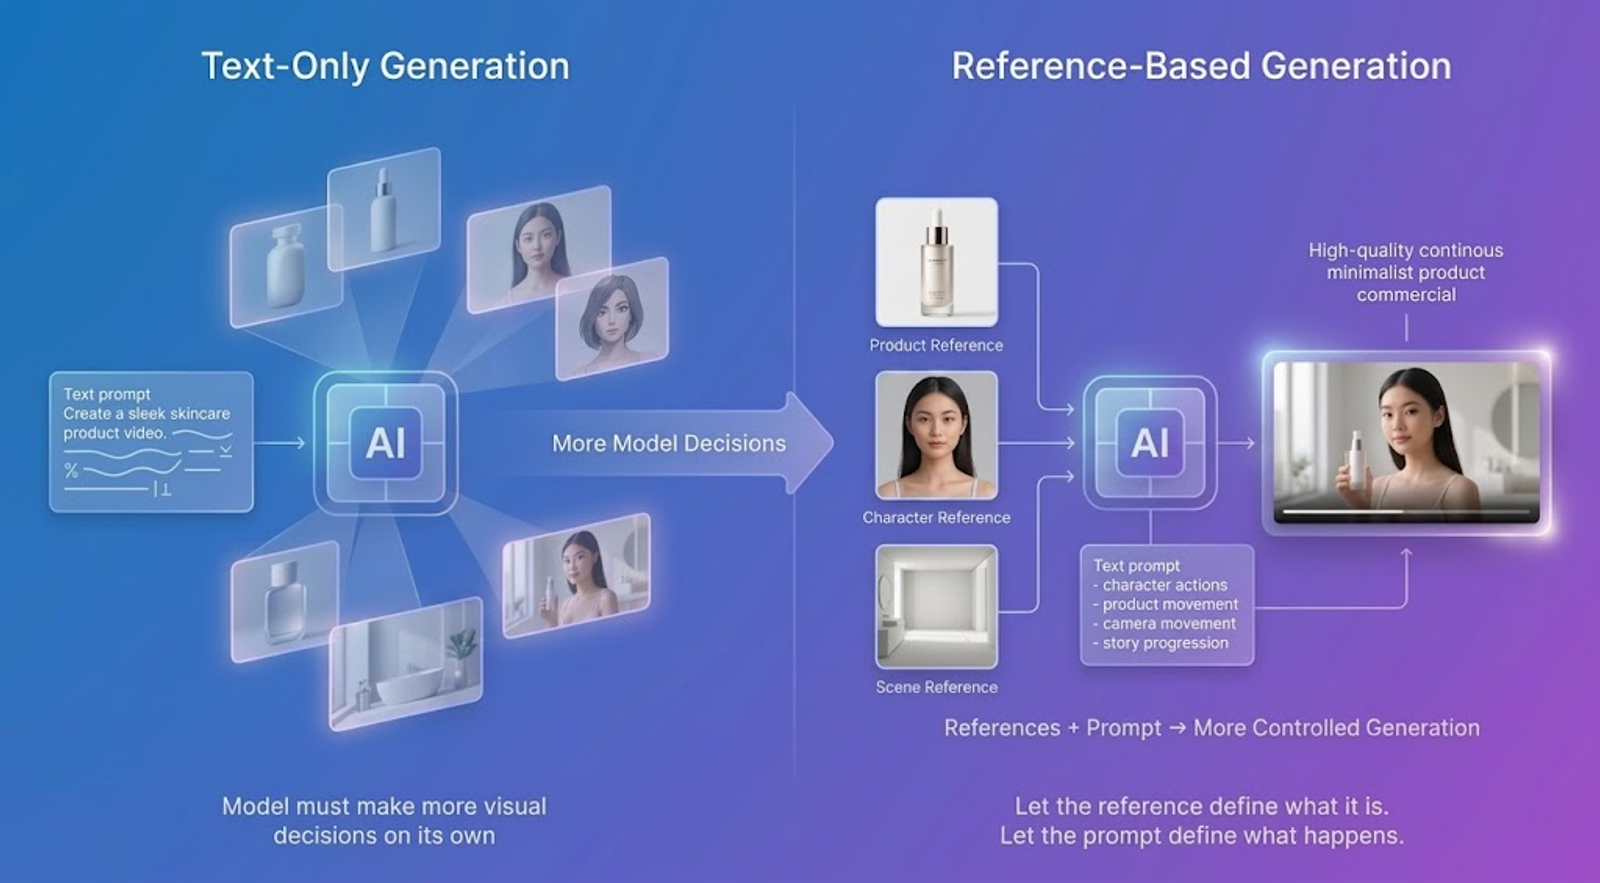
Reference-Based Generation Is More Controllable Than Text-Only Generation
This is probably the biggest conclusion I reached after repeatedly testing Seedance 2.5.
If I have two options:
A. Generate everything from scratch using text only.
B. Give the model a product image, character reference, or scene reference and then generate from it.
For projects with clear visual requirements, I usually prefer B.
The reason is straightforward:
Text-only generation leaves more decisions to the model.
The model has to interpret what the person looks like, what the product looks like, what the environment looks like, how the composition should work, and so on.
Once I add a visual reference, some of those decisions are already grounded in an actual image.
If I have a product image, the product's appearance is already established.
If I have a character reference, the character's visual identity has a concrete reference.
If I have a scene image, the environment and spatial relationships have something to work from.
That means the prompt can focus more on:
What the character does.
How the product moves.
How the camera moves.
How the story progresses.
This is one reason I don't rely entirely on text-to-video when creating product content in Wizstar.
If I already have product images or brand assets, I can use them as references through Wizstar's reference-to-video, first-frame, or start-and-end-frame workflows, then use the prompt to control the action and camera direction.
For e-commerce content, that workflow makes a lot of sense to me.
In real projects, you usually already have product images, brand assets, or other visual materials. The challenge isn't necessarily creating those assets from nothing. It's turning those existing assets into a finished video.
For example, if a product image already establishes the packaging and appearance, I would rather let the image define what the product looks like and use the prompt to define how the product is presented.
That creates a useful division of responsibility:
Reference materials provide visual constraints.
The prompt provides creative direction.
Of course, reference-based generation isn't guaranteed to work perfectly every time. Character movement, product details, continuity, and other visual elements still need to be checked.
But compared with starting entirely from text, I find that the model has fewer things to guess.
So this is the principle I now use most often:
If something can be clearly established with a reference image or video, establish it with the reference first. Use the prompt to create what needs to happen next.
What I Actually Took Away From Testing Seedance 2.5
After going through the official prompt guidance and running several rounds of Seedance 2.5 tests in Wizstar, I think the biggest lesson is actually pretty simple:
A good AI video prompt isn't about giving the model more information. It's about reducing the amount of information the model has to guess.
If the subject and action are unclear, clarify them.
If you already have reference assets, explain what each one controls and what it shouldn't control.
If you're creating a longer video, divide it into stages and describe how each stage connects to the previous one.
If a character needs to express an emotion, turn that emotion into specific actions.
And if you already have product, character, or scene references, use them instead of asking the model to invent everything from scratch.
After all the testing, these are the five Seedance 2.5 prompt techniques I would keep:
Get the prompt order right before adding more detail.
Give every reference asset a clear role and boundary.
Break long videos into stages and carefully describe the continuity between them.
Use concrete actions to express emotions.
Use reference-based generation when you need more control than text-only generation can provide.
If you're currently experimenting with Seedance 2.5 for product ads, brand videos, or other AI video projects, I'd start simple. Take one product image or character reference, define exactly what it controls, then build the action and camera direction around it. In Wizstar, you can also move from those reference assets into Seedance 2.5 video generation and test different prompt variations without having to rebuild the entire workflow from scratch.
That's the workflow I've found most practical so far.
Give the model fewer things to guess first. Then worry about making the video more ambitious.